How to Rank in Claude: The Citation Playbook That Works
SearchBlueprint · · 9 min read · scored 92/100
How to rank in Claude is a citation problem, not a ranking problem. Let Anthropic's crawler read your site, answer one question in the first 60 words under every heading, and back your claims with named sources. Claude quotes passages, not pages, so the best-structured answer wins the mention.
This guide is for site owners, marketers, and content teams who want their pages cited when Claude answers questions in their niche. The tactics below apply whether people reach Claude at claude.ai, inside enterprise tools that embed it, or through the growing share of buyers who ask an assistant before they ever open Google.
Ranking in Claude is not ranking in Google
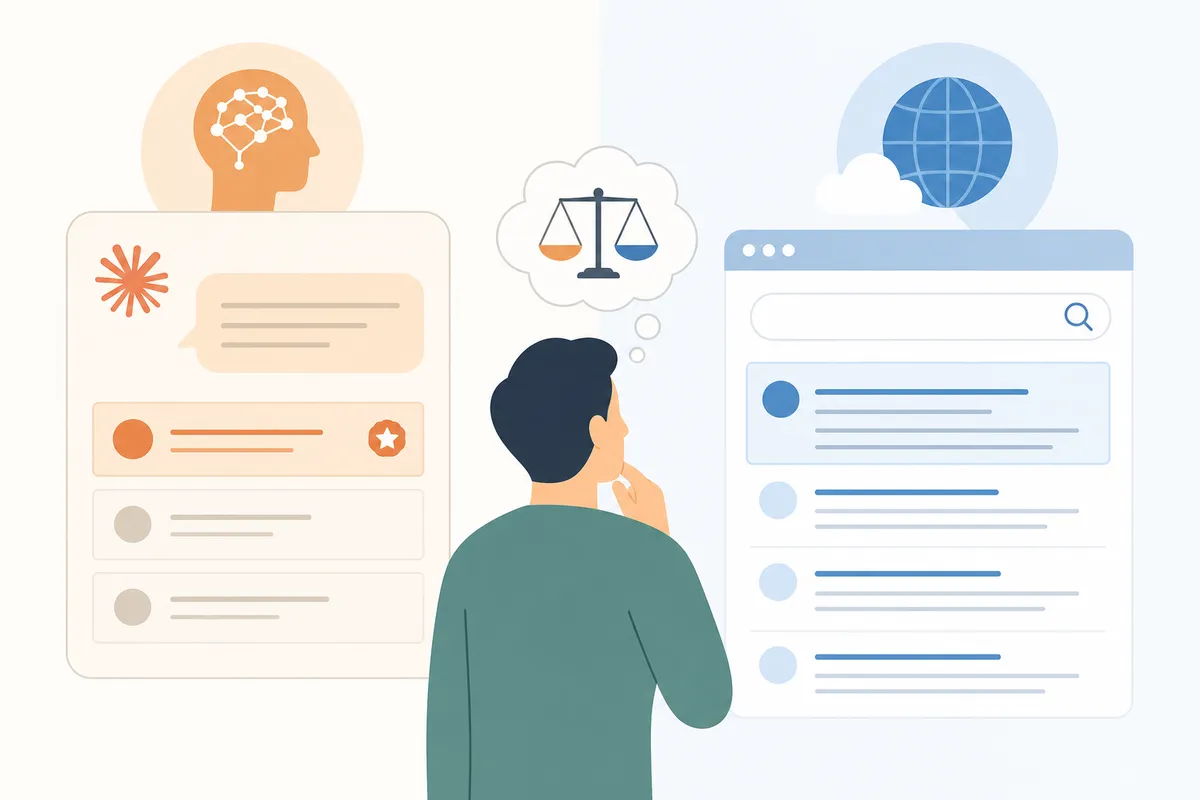
Traditional SEO gets a page into a ranked list. Claude does something different: it reads several sources, writes one synthesized answer, and names the sources it leaned on. Your page never appears as a blue link. A paragraph from it either gets woven into the answer, with a citation, or it does not exist.
That changes what wins. Google can reward a strong domain with a mediocre page. Claude is choosing between passages, so a focused 50-word answer on a modest site can beat a rambling section on a bigger one. You are formatting answers for extraction now, not optimizing pages for a crawl.
| Dimension | Google search | Claude answers |
|---|---|---|
| Unit that competes | The whole page, ranked in an ordered list of results | The individual passage, quoted or paraphrased inside one synthesized answer |
| What gets rewarded | Authority, links, and relevance signals accumulated by the page and domain | Passages that answer the exact question directly, with sources and specifics attached |
| Where visibility shows up | A position you can track daily with a rank checker | A citation or brand mention inside an answer, which varies with how the question is phrased |
| Cost of vague writing | A weaker ranking you can still partly buy back with links | Exclusion: a passage that hedges or rambles is simply not quotable |
| Effect of keyword stuffing | A spam signal that can suppress the page | Princeton's GEO research reports roughly a 10 percent visibility loss from stuffing |
How Claude finds and cites sources
Claude draws on three routes, and each one is a separate door your content can walk through.
Three routes into an answer
First, training data. Claude carries broad knowledge of the public web up to its training cutoff. Content that has been live, linked, and consistent for a long time shapes what the model already believes about your category.
Second, live web search. When a question needs current information, Claude searches, reads a handful of results, and cites the pages it used. This is the route you can influence fastest, because it behaves like a very picky reader rather than a ranking algorithm.
Third, supplied documents. Anthropic's developer platform includes a citations capability that ties answer sentences back to exact passages in documents an application provides. Enterprise products built on Claude use patterns like this, which is one reason industry coverage describes Claude as the editorial engine of AI search, embedded inside tools from major enterprise brands and handling hundreds of millions of queries a month.
What Claude prefers to quote
Across all three routes the same traits keep winning: a direct answer stated early, a specific figure with a named source, a clear author, and a page whose structure makes the passage easy to isolate. PR industry analysis of Claude's citation behavior describes it as valuing different things than ChatGPT, with a tilt toward editorial, well-attributed material. You do not need to verify that framing to act on it, because everything it recommends is also just good publishing.
How to write passages that rank in Claude
One widely shared workflow comes from a founder who spent 60 days building a blog agent, then watched his product get cited first in Claude, ChatGPT, and Perplexity. His pipeline hard-codes five rules into every post, and they match what the research says. Here they are, synthesized and stripped of the automation.
Put the answer in the first 60 words under every heading
AI engines extract passages. If the first sentences under a heading are throat-clearing, the extractable answer lives somewhere Claude will not look. Write a 40 to 60 word direct answer at the top of each H2, then expand below it. Read the opening paragraph of this article again: that is the pattern, applied.
Make statistics and named sources do the work
The strongest published evidence on this is the GEO study from Princeton researchers, available on arXiv. Its reported effects, as practitioners cite them:
| Tactic | Reported effect on LLM citations | How to apply it |
|---|---|---|
| Adding statistics | Around a 37 percent lift, per the Princeton GEO study | Replace "many businesses" with a real counted figure from a source you can name |
| Citing sources inline | Around a 40 percent lift, the largest reported gain | Name the organization and link it in the sentence where the claim appears, not in a footnote |
| Including expert quotes | Around a 30 percent lift | Quote a named person with credentials, not "experts say" |
| Keyword stuffing | Around a 10 percent visibility loss | Delete repeated exact-match phrases; they now cost you citations as well as rankings |
The old playbook of squeezing a phrase into every paragraph is not just useless here. By these numbers it is actively harmful. You can read the study itself at arXiv, GEO: Generative Engine Optimization.
Add a TL;DR at the top and a FAQ at the bottom
Practitioners tracking their own citations report that these are the two most-quoted blocks on any post. The summary gets pulled for "give me the gist" questions, and the FAQ gets pulled for long-tail phrasings. Write both so each one stands alone with no context, because that is exactly how an answer engine will use them. The format overlaps heavily with what wins featured snippets, and our guide to answer engine optimization walks through the block-by-block structure.
The technical checklist Claude visibility depends on
None of the writing advice matters if Claude cannot fetch the page. Work through this list before touching a single paragraph:
- Allow ClaudeBot in robots.txt. Anthropic's crawler identifies itself, and its official crawler documentation confirms that a disallow rule removes you from consideration. Check your server logs to confirm it actually visits.
- Serve readable HTML without JavaScript. Fetch your page with a plain HTTP client. If the article body is missing until scripts run, assume an AI crawler sees the empty version.
- Keep a clean heading hierarchy. One H1, descriptive H2s and H3s, no heading levels skipped. Extraction depends on structure.
- Ship Article and FAQPage schema. Structured data is a trust and parsing signal, not a magic switch. It tells the engine what the page is and who wrote it.
- Show a named author and a visible updated date. Byline with credentials near the top. Anonymous, undated pages give an engine nothing to weigh.
- Keep the sitemap current and response times fast. A current sitemap is how crawlers discover your pages in the first place, and slow or erroring pages get sampled less on every crawler, AI or otherwise.

Build a cluster Claude can follow
Single orphan posts rarely get cited. The pattern that keeps showing up in practitioner write-ups is one comprehensive pillar page plus three or four tighter cluster posts, each linking back to the pillar with a bridge sentence such as "the broader strategy behind this sits in our main guide." Language models follow that topical graph, and the node with the most connected signal collects the citations.
The same architecture pays off across every engine at once. Passages built this way surface in ChatGPT and Gemini too, and the differences between platforms are smaller than the fundamentals they share; we break down the per-engine quirks in our post on getting your site cited by ChatGPT and Gemini.
How to test whether you rank in Claude
You cannot manage what you never measure, and Claude has no Search Console. Build your own measurement loop instead.
A weekly testing routine
- Write down 10 questions a ready-to-buy customer in your niche would actually ask, phrased three different ways each.
- Ask them in a fresh Claude session each week, with web search available, so past conversation context cannot contaminate the answers.
- Log which domains get cited for every question, yours and competitors'.
- When a competitor is cited and you are not, open their page and compare the passage that won against yours. The gap is usually structural: they answered in 50 words where you took 400.
- Track the trend monthly. Citation share moves in weeks, not days.
What the hype gets wrong
The YouTube ecosystem around this topic is loud. One widely watched video, at 59,000 views, is titled "Using Claude Code SEO to Rank #1 in 24 hours" and lists a $1,600 a month service; others promise ranking overnight or automating 99 percent of the work. Treat every claim like that as a sales pitch. Claude's citation behavior shifts with model updates, question phrasing, and what it finds on any given search, so nobody controls it on a 24-hour timeline. The honest version of this work is unglamorous: fix the technical floor, restructure your passages, add the sources, and check the log weekly.
FAQs
Does ranking in Google help you rank in Claude?
Partly. When Claude searches the web it tends to read pages that search engines already surface, so Google visibility feeds the pipeline. But extraction decides the citation, which is why practitioners report being quoted from page 2 or 3 positions while page 1 results get skipped.
How long does it take to get cited by Claude?
There is no fixed timeline. Pages reached through live web search can start appearing in answers soon after they are indexed and crawlable, while influence on the model's baked-in knowledge moves on training-cycle timescales. Plan in weeks and months, and ignore anyone quoting hours.
Can you pay to appear in Claude's answers?
No. There is no ad product inside Claude's answers today. Services selling "guaranteed Claude rankings" are selling the same content and technical work described in this guide, sometimes competently, never with a guarantee they can enforce.
Do you need schema markup to rank in Claude?
It is not a strict requirement, but Article and FAQPage schema make the page easier to parse and signal authorship and freshness, which are the trust markers AI engines keep favoring. Given the low cost, there is no good reason to skip it.
Should you block or allow ClaudeBot?
Allow it if you want citations. Blocking Anthropic's crawler removes your pages from consideration when Claude searches the web, and it does nothing to remove knowledge already in the model. Publishers with a licensing strategy are the main group with a reason to block.
Get a baseline before you rewrite anything
Start with an audit rather than a guess, because half of Claude visibility is technical problems you cannot see from the browser. Talk to the team and look through a sample SEO report built from a real site crawl to see which of your pages already carry quotable passages and which fail the checklist above. Working out how to rank in Claude gets much faster once you know exactly which fixes your own site needs first.
Resources / References
- citations capability
- arXiv, GEO: Generative Engine Optimization
- official crawler documentation
- Structured data
- how crawlers discover your pages
Sources
About the author
SearchBlueprint researched, wrote and scored this article with the content pipeline our customers run on their own sites. The score in the byline is what our content engine gave this page before it published. Nothing here is reviewed by hand, which is the point: it is the product's output, published where anyone can check it.